 Cloud & AI Infrastructure
 Dev Ops Live
 Cyber Security World
 Big Data & AI World
 Data Centre World
Exhibitor Products
TuringData ContextCube
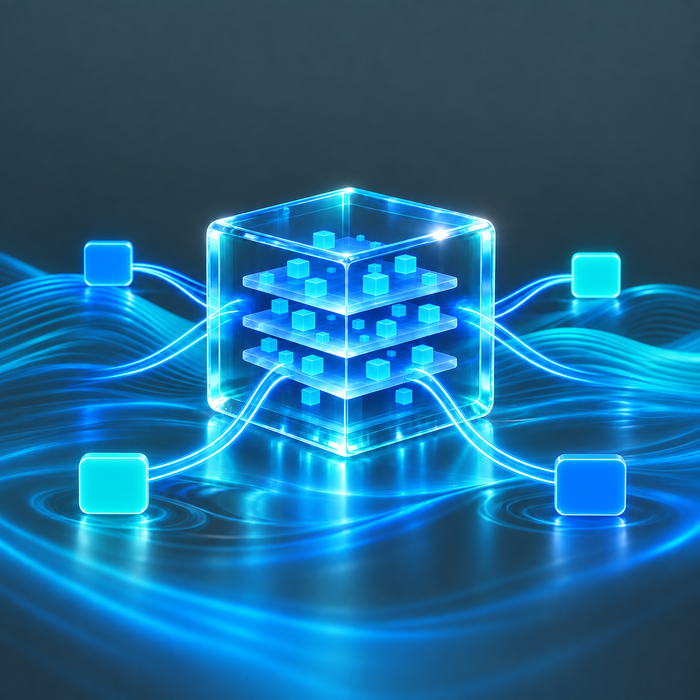
As inference clusters grow, valuable KV cache is often isolated within individual servers and evicted when local capacity fills. ContextCube provides a dedicated shared cache tier connected to participating nodes, giving reusable context a common home across the cluster.
Inference nodes retrieve matching cached prefixes over RDMA, while storage services run on NVIDIA BlueField-3 DPUs to move KV data with less host CPU involvement. With hundreds of terabytes of shared capacity available by configuration and up to 120 GB/s reference bandwidth per appliance, ContextCube helps retain reusable context longer and reduce redundant computation.
It works with inference engines such as vLLM and SGLang and connects to KV cache software including TuringData Cache Fabric, LMCache, and Mooncake. This open design supports agents, coding assistants, multi-turn conversations, long-document and RAG workloads, and high-volume token factories.